When a customer asks, "Am I eligible for the bank's newly introduced home loan scheme?" Without RAG, the AI answers based on an older version of the home loan policy or on eligibility criteria learned during training. But, with RAG, the AI retrieves the latest approved loan policy from the enterprise knowledge base and generates a response based on the current version, ensuring customers receive accurate, up-to-date information.
This approach fundamentally changes how enterprise AI delivers information. Rather than relying on static knowledge stored in the model, enterprise RAG connects AI to dynamic knowledge repositories, including internal documentation, knowledge bases, policy manuals, product catalogs, case records, and other enterprise systems. As business information evolves, AI can continue providing responses based on the most up-to-date content without requiring the model to be retrained.
In the previous blog, we discussed the challenges an enterprise faces due to LLM drawbacks, such as hallucinations and a lack of personalization, and why an enterprise can’t afford to train its own LLMs.
Now, let’s see what Retrieval-Augmented Generation is, how it works at the enterprise level, and its benefits.
As enterprises began to deploy AI across business workflows, they needed AI that could deliver answers that reflect the latest business policies, enterprise knowledge, and customer context. This is where RAG helps. Instead of relying solely on information learned during training, the model accesses current, organization-specific content when a user asks a question. The retrieved information is then used as context for the LLM to generate an accurate and relevant response.
RAG is an architecture that helps optimize the LLM context by combining it with an external knowledge base. This helps generate accurate answers and reduces the risk of unsupported responses, improves grounding, and makes answers easier to verify.
When a customer asks whether they are eligible for a newly launched mortgage product, the enterprise RAG first retrieves the latest lending policy rather than relying on historical training data. It checks recent policies, eligibility criteria, and product documentation from the bank's trusted knowledge sources. The LLM then generates a response using this information, reflecting the bank's most up-to-date guidelines. This ability to ground AI responses in trusted enterprise knowledge is one of the key benefits of RAG in enterprise AI. It helps organizations improve response accuracy, reduce hallucinations, and deliver context-aware responses.
In the next section, we'll look at what happens behind every enterprise AI response and explore how RAG works, from indexing enterprise knowledge to generating a context-aware answer.
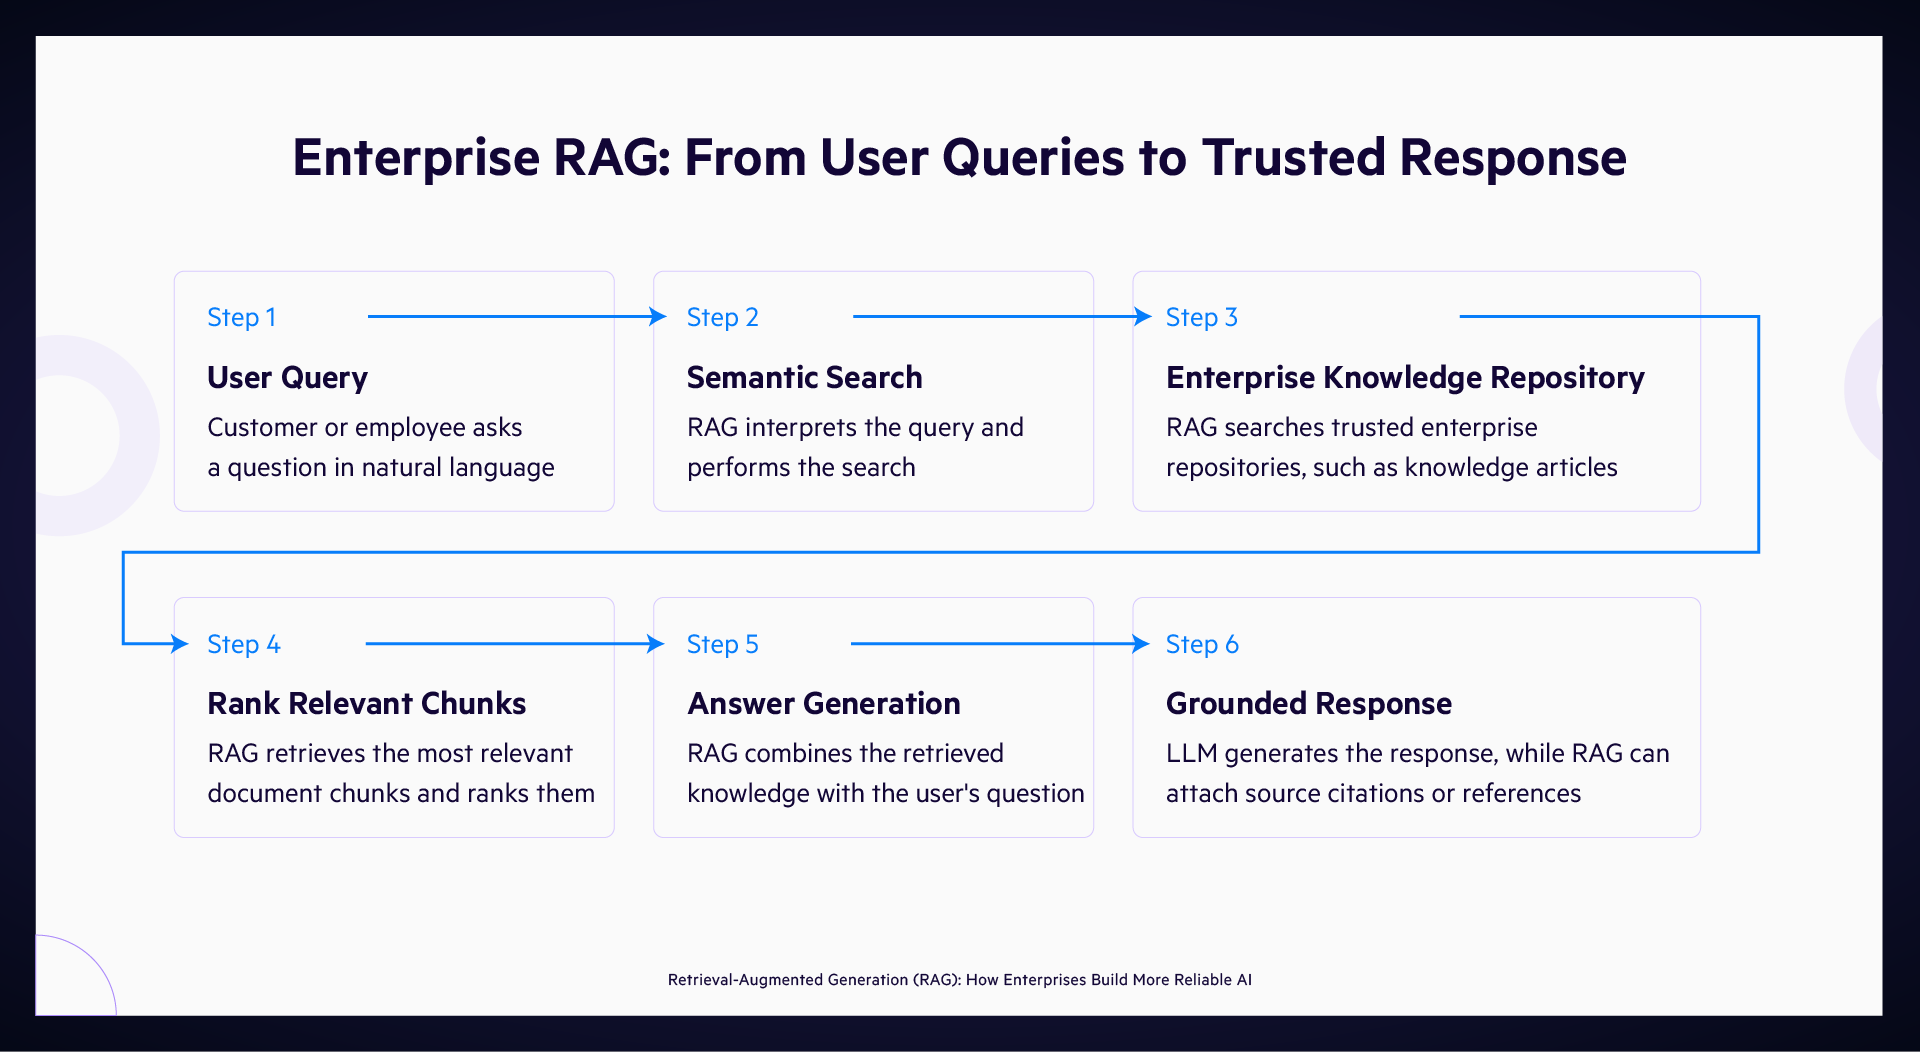
Although an AI assistant delivers responses within seconds, several stages take place behind the scenes to generate an accurate, context-aware response. This is where enterprise RAG plays a critical role.
This process typically consists of five key stages:
Before enterprise RAG can retrieve relevant information, enterprise knowledge must first be prepared for efficient search. In the indexing stage, various documents, such as knowledge articles, policy manuals, product documentation, FAQs, and standard operating procedures, are gathered and processed to extract their relevant content. The content is then divided into smaller chunks, converted into vector embeddings, and indexed in a vector database, creating a searchable enterprise knowledge foundation. This enables the retrieval engine to identify information based on the intent and context of a user's query.
Once the enterprise knowledge has been indexed, the enterprise RAG system is ready to retrieve information when a user submits a query. For example, if a customer asks, "Am I eligible for the bank's new home loan scheme?", the system first analyzes the intent behind the question rather than relying solely on the exact words used.
The retrieval engine identifies the knowledge of chunks that are semantically most relevant to the user's query, even when they don't contain the exact keywords. Rather than retrieving a single document, RAG typically returns multiple relevant chunks from enterprise knowledge repositories.
However, not every retrieved chunk carries the same level of relevance. During the ranking stage of the ranking, the results are evaluated and reordered based on factors such as semantic relevance, contextual similarity, and retrieval confidence scores. The highest-ranked chunks are then selected and prioritized before being passed to the LLM. By filtering out less relevant information and prioritizing the most meaningful content, RAG helps to optimize the LLM's context window and improve the accuracy of the final response. This is one of the key benefits of RAG in enterprise AI, particularly when organizations manage large volumes of enterprise knowledge across multiple repositories.
The LLM generates the response using trusted enterprise knowledge rather than relying solely on the knowledge learned during training. By grounding the LLM with current business policies, product documentation, and organization-specific knowledge, RAG helps reduce hallucinations, improve factual accuracy, and generate responses that align with the organization's latest information.
After generating the response, the LLM returns the final output to the application, where it is presented to the user through an AI assistant, chatbot, enterprise search portal, or business application. Depending on the implementation, the response may also include citations, source references, or links to the retrieved knowledge articles, allowing users to verify the information and explore the original content.
This process enables RAG to ground the LLM with context retrieved from enterprise repositories, resulting in responses that are accurate, relevant, and aligned with current business knowledge.
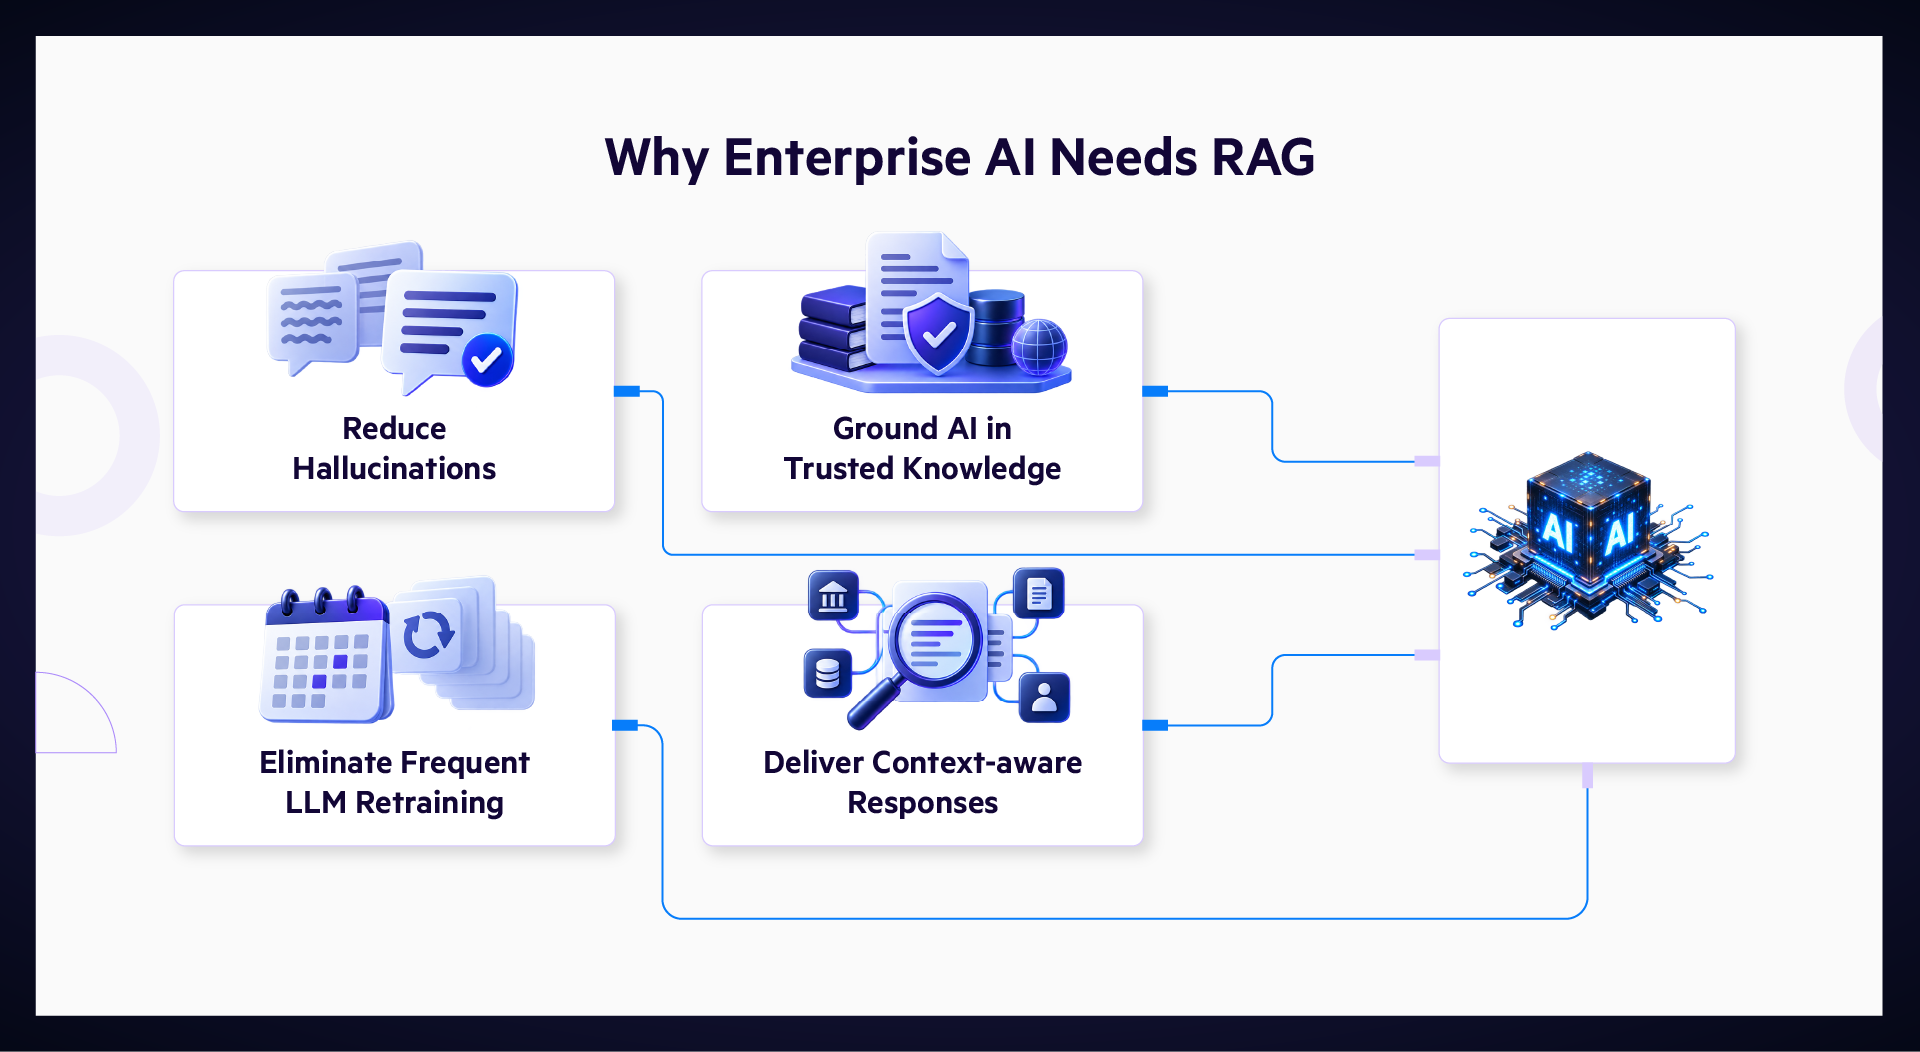
Enterprises planning to deploy generative AI need more than standalone LLMs to overcome their limitations. RAG addresses these challenges by combining the language capabilities of LLMs with trusted enterprise knowledge. Some of the key benefits of RAG in enterprise AI include:
The global RAG market is projected to grow from USD 1.94 billion in 2025 to USD 9.86 billion by 2030, reflecting the increasing enterprise adoption of AI architectures that combine LLMs with trusted knowledge retrieval.
Organizations cannot rely on AI that generates inaccurate responses, uses outdated business information, or lacks visibility into the sources behind its answers.
RAG addresses the knowledge challenge by grounding every AI response in approved enterprise repositories instead of relying solely on an LLM's training data. This helps reduce hallucinations, improve response accuracy, and ensure AI reflects the organization's current business knowledge.
To operationalize AI in enterprise environments, organizations need a governance layer that ensures information is retrieved only from approved repositories, enforces role-based access controls, protects sensitive data, and supports regulatory compliance. These controls help ensure AI responses remain secure, consistent, and aligned with organizational policies.
RAG represents a significant step forward in making generative AI practical for enterprise use. Rather than relying solely on an LLM's training data, RAG enriches AI with trusted, organization-specific knowledge at the time of a user's query. This enables AI to deliver responses that are more accurate, relevant, and aligned with current business information. As enterprises continue to adopt generative AI, success will depend on the quality and accessibility of the knowledge that supports it. By combining language generation with trusted enterprise context, RAG helps organizations reduce hallucinations, improve decision-making, and build greater confidence in AI-driven interactions.